
Table of Contents
- Who This Guide Is For
- Four Concepts You Need First
- Step 1: Install RAGFlow
- Step 2: Build Your First Knowledge Base
- Step 3: Choose the Right Chunking Method
- Step 4: Create an Assistant and Ask Real Questions
- Step 5: Tune What Is Actually Broken
- Step 6: Add GraphRAG When You Need It
- A Realistic First Week
- Five Settings Worth Understanding
- Troubleshooting the Six Common Failures
- Where to Go Next
- Final Thoughts
- Frequently Asked Questions
Most RAGFlow tutorials stop at “you have successfully deployed the container.” That is the easy part. The hard part is the week afterwards, when your assistant confidently answers a question using a document from 2021 and you have no idea why.
This guide covers both. By the end you will have RAGFlow running, a knowledge base that returns accurate answers, and – more importantly – a working understanding of which knob to turn when it does not.
Who This Guide Is For
You should be comfortable running a Docker command and editing a config file. You do not need to know what an embedding is, what HNSW stands for, or how a transformer works. RAGFlow is designed so that you can build something genuinely useful without any of that.
If you have not yet decided whether RAGFlow is the right tool at all, our overview of how the RAG engine works is a better starting point than this one.
Four Concepts You Need First
Skip these and the interface will not make sense. Read them once and everything clicks.
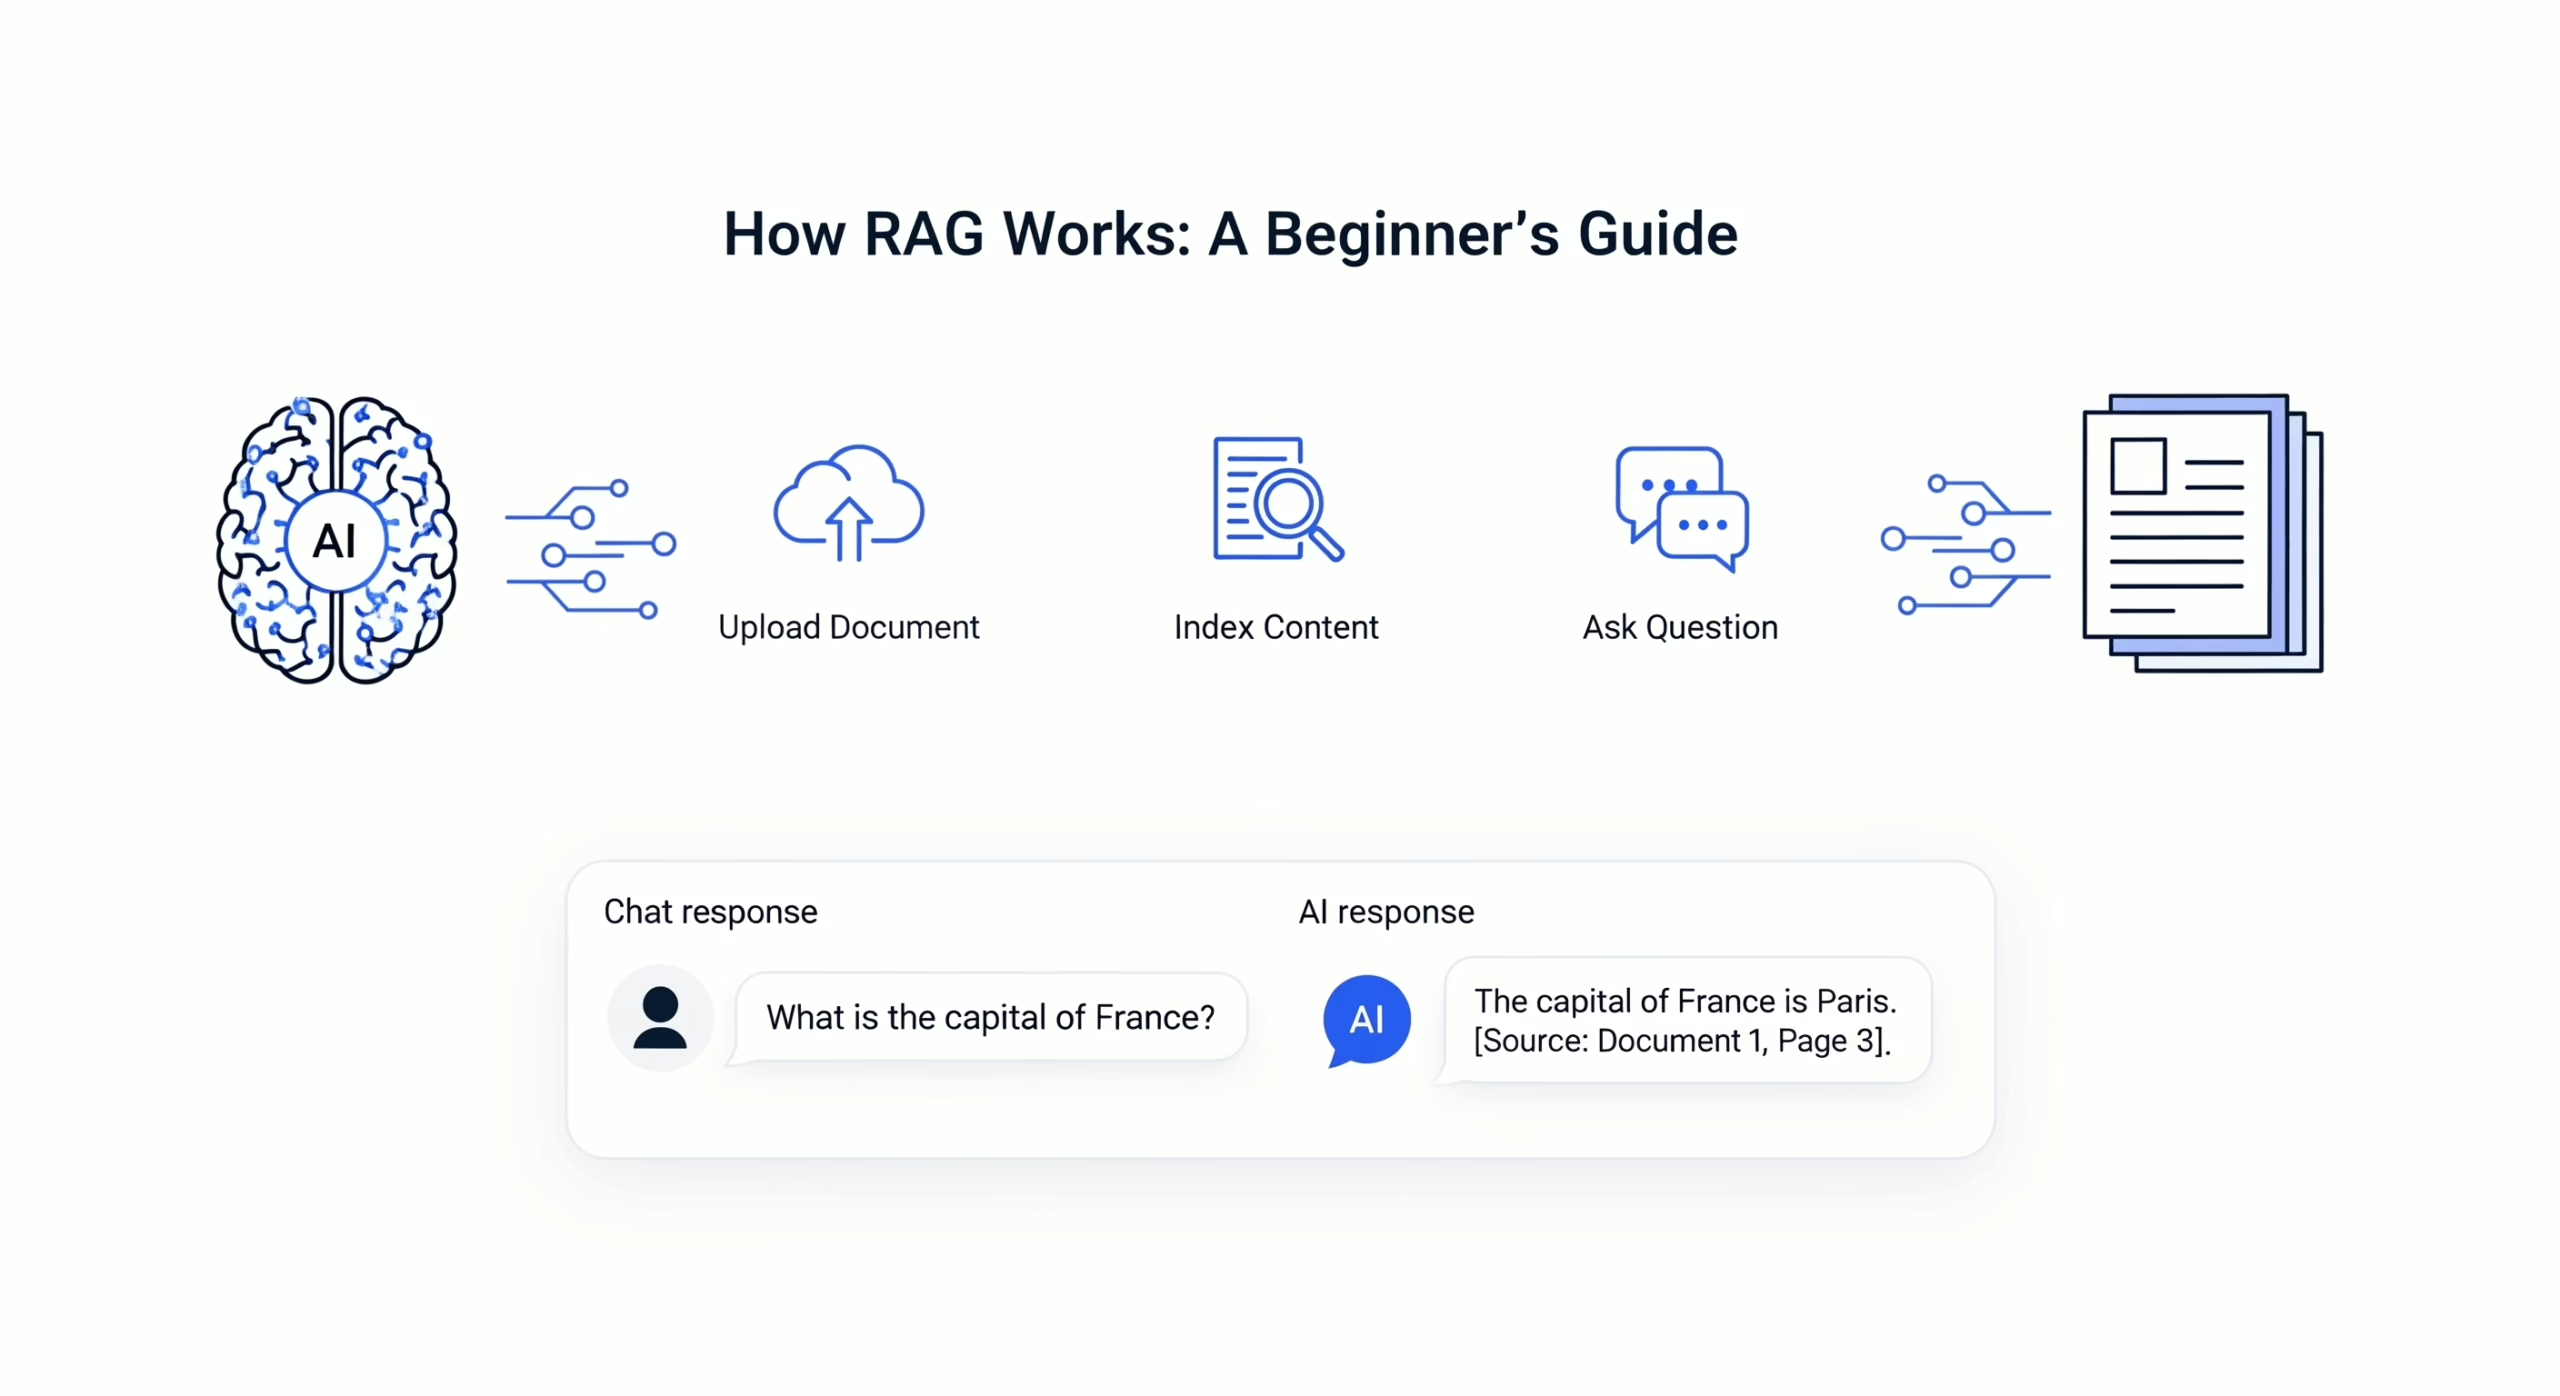
Knowledge base. A collection of documents that get parsed, chunked and indexed together. Think of it as a folder that has been made searchable by meaning rather than filename. You will usually want several – one per topic or department – rather than one giant one.
Chunking. Documents get split into pieces before indexing. Chunk badly and a table gets severed down the middle, or a heading gets separated from the paragraph it introduces. RAGFlow gives you templates for this instead of one blind splitter, which is the single most useful thing it does for beginners.
Retrieval. When you ask a question, the system finds the chunks most likely to contain the answer. It does not read your whole library – it retrieves a handful of pieces and shows them to the model.
Assistant. The chat configuration that sits on top: which knowledge bases it can see, which model it uses, what its system prompt says, how many chunks it retrieves. One knowledge base can serve several assistants with different personalities and permissions.
Step 1: Install RAGFlow
The official RAGFlow documentation covers the full option list. Check your hardware first. The minimum realistic setup is 4 CPU cores, 16GB RAM and about 50GB of free disk. It will technically start on less and the experience will be miserable.
Make sure Docker and Docker Compose are installed, then clone the repository from GitHub and start the stack from the docker directory. The first run pulls several gigabytes of images, so make coffee.
Two things trip people up here.
The vm.max_map_count setting. On Linux the search backend needs this raised. If the container restarts in a loop on first boot, this is almost always why. Raise it to at least 262144 and make the change persistent, or it resets on reboot.
The image variant. RAGFlow publishes a slim image and a full image. The slim one downloads faster but does not include embedding models, which means it fetches them at runtime. If you are working somewhere with restricted outbound access, take the full image.
Once the stack is healthy, open the web interface, register the first account – which becomes the admin – and you are in. Total time on a decent connection: thirty to forty minutes, most of it downloading.
Step 2: Build Your First Knowledge Base
Resist the urge to upload everything you own. Start with ten to twenty documents you know intimately, because you need to be able to spot a wrong answer instantly.
Before uploading, set the embedding model on the knowledge base. This matters more than it appears: changing it later forces a full re-index of every document. Pick one and commit.
Then upload and hit parse. Watch the parsing results rather than walking away – RAGFlow shows you exactly how each document was broken up, and this is the most informative screen in the entire application.
Look specifically at whether tables survived as tables, whether headings stayed attached to their sections, and whether any document produced one enormous chunk or hundreds of tiny ones. Both extremes signal the wrong chunking method, which is the next step.
Step 3: Choose the Right Chunking Method
This is where beginners gain or lose most of their answer quality, and it takes about two minutes to get right.
| Document type | Use this method | Why |
|---|---|---|
| Reports, articles, manuals | General | Sensible default that respects layout |
| Academic papers | Paper | Understands abstract, sections, references |
| Books, long PDFs | Book | Handles chapter structure and long-range context |
| Contracts, policies | Laws | Preserves clause and article numbering |
| Slide decks | Presentation | Treats each slide as a coherent unit |
| FAQ documents | Q&A | Keeps each question with its answer |
| Spreadsheets, price lists | Table | Preserves rows and column headers |
| Scanned or photographed pages | Picture | Runs OCR before chunking |
One more setting worth enabling on important knowledge bases: auto-keyword and auto-question extraction. RAGFlow generates likely search terms and questions for each chunk, which measurably improves retrieval on documents where the wording of a question differs from the wording of the source. It costs a little processing time at parse and pays back on every query.
Step 4: Create an Assistant and Ask Real Questions
Create an assistant, connect your knowledge base, choose a model. If you have an API key for a hosted provider use it for now; you can move to a local model later once you know the system works.
Write a system prompt that constrains behaviour rather than describing personality. Something like: answer only from the provided context, cite the source for every claim, and if the answer is not in the documents say so explicitly rather than guessing.
That last instruction is the difference between a useful assistant and a liability. Without it, RAGFlow will happily fill gaps with plausible invention.
Now ask fifteen or twenty real questions – ones you already know the answers to. Ask easy ones, ambiguous ones, and at least three whose answers are genuinely not in the documents. That last category tells you whether your guardrail is working.
Step 5: Tune What Is Actually Broken
Do not tune randomly. Diagnose first: click into the citations on a bad answer and look at which chunks were retrieved.
If the right chunk was retrieved but the answer was wrong, the problem is your prompt or your model. Tighten the system prompt first – it is free.
If the right chunk was not retrieved at all, the problem is retrieval. Raise the number of chunks retrieved, lower the similarity threshold, or enable reranking. Reranking is the highest-return single change available to most beginners: retrieve more candidates, then let a reranker pick the best few.
If the retrieved chunk is garbled or truncated, the problem is chunking. Go back to step three and change the method, then re-parse.
If answers cite outdated documents, the problem is curation, not configuration. Remove the stale files. No amount of tuning fixes a knowledge base full of superseded policies.
Change one variable at a time and re-run your question set after each change. It is slower and it is the only way to know what actually helped.
Step 6: Add GraphRAG When You Need It
GraphRAG builds a knowledge graph of entities and relationships across your dataset rather than relying on similarity alone. In current versions the graph is constructed across an entire dataset and updates automatically as new files are parsed.
Turn it on when your questions span multiple documents – “which of our suppliers are affected by this policy change” rather than “what does this policy say.” Leave it off for straightforward lookup, because it adds meaningful processing time at parse and does not improve simple retrieval.
Most beginners enable it too early, wait a long time for parsing, and see no improvement. Get standard retrieval working well first.
A Realistic First Week With RAGFlow
Expectations cause more abandoned projects than technical problems do. Here is what a genuinely productive first week looks like.
Day one: get it running, change nothing. Install RAGFlow, upload ten documents, accept every default, ask five questions. The goal is a working baseline, not a good one. Resist configuring anything.
Day two: write your question set. Twenty real questions with known answers, written down in a document. This is the most valuable hour you will spend, and almost everyone skips it. Without it you cannot tell whether a change helped, and you will end up making adjustments based on how the last answer felt.
Day three: fix chunking. Run your question set, look at the citations behind every failure, and change the chunking method on the documents that produced garbled context. Re-parse. Run the set again. This one change typically produces the largest single improvement a beginner sees in RAGFlow.
Day four: tighten the prompt and enable reranking. Two cheap changes with outsized effects. Your system prompt should forbid guessing explicitly, and reranking should sit between retrieval and generation.
Day five: curate. Remove superseded documents. Split one overloaded knowledge base into two focused ones. This is unglamorous and it is usually where the last stubborn twenty percent of wrong answers disappears.
The weekend: leave it alone. Come back Monday and run the question set cold. Problems you had stopped noticing become obvious again.
Teams that follow roughly this sequence end week one with something trustworthy. Teams that spend day one enabling every advanced feature in RAGFlow usually end it with a slow system and no idea which change caused which behaviour.
Five RAGFlow Settings Worth Understanding
You can ignore most of the configuration surface. These five you cannot.
1. Similarity threshold. The minimum relevance score a chunk needs to be considered. Set it high and RAGFlow refuses to answer questions it could have answered. Set it low and it drags in loosely related material. Start around the default, then move it based on which failure mode you are actually seeing.
2. Top-N chunks. How many pieces get passed to the model. More context is not automatically better – past a certain point the relevant chunk gets buried among mediocre ones and answer quality drops. If you have reranking on, retrieve generously and let the reranker narrow it.
3. Keyword similarity weight. RAGFlow blends semantic similarity with keyword matching. Corpora full of product codes, error numbers, surnames or part references want more keyword weight. Prose-heavy corpora want less. This setting quietly rescues a lot of “why can it not find this exact term” complaints.
4. Reranking model. Off by default in many setups, and it should not be. A reranker re-scores retrieved candidates with a model that reads the question and the chunk together rather than comparing pre-computed vectors. It costs a few dozen milliseconds and improves precision more reliably than any other single toggle in RAGFlow.
5. Multi-turn context. Whether the assistant rewrites follow-up questions using conversation history. Enable it for chat-style use, because “what about the second one” is meaningless as a standalone query. Disable it for one-shot API calls where each request is independent.
Everything else in the interface can wait until you have a reason to touch it. Beginners who methodically work through these five settings get further with RAGFlow than those who read the entire documentation first.
Troubleshooting the Six Common Failures
Containers restart in a loop. Almost always vm.max_map_count on Linux, or insufficient memory allocated to Docker on Mac and Windows.
Parsing hangs at zero percent. Usually the embedding model failed to download. Check the container logs and confirm outbound access, or switch to the full image.
Every answer is “I could not find that.” Your similarity threshold is too high. Lower it substantially and work back up.
Answers mix unrelated topics. Too many chunks retrieved, or several unrelated knowledge bases attached to one assistant. Separate them.
Tables return nonsense. Wrong chunking method. Re-parse those documents with the Table or General method.
It is unbearably slow. Parsing is CPU and GPU bound; querying is model bound. Identify which phase is slow before buying hardware – people frequently upgrade the wrong thing.
Where to Go Next
Once the basics work, three directions are worth your time.
Automate the ingestion. Manually uploading files does not scale. Wiring document arrival to parsing through n8n AI agents turns this from a chore into a pipeline.
Understand the storage layer. RAGFlow handles this for you, but knowing how retrieval actually works makes tuning far less mysterious – our guide to vector databases for RAG covers the fundamentals.
Plan the production deployment. Evaluation on a laptop and a system a department depends on are different projects. The sizing and backup logic in our self-hosting guide applies almost directly, and for the strategic picture see our breakdown of RAGFlow in enterprise deployments.
Final Thoughts
The thing nobody tells beginners is that RAGFlow is not difficult – it is just unforgiving about the parts people want to skip. Curating documents is dull. Writing a question set is dull. Reading citations to work out why an answer was wrong is dull. All three matter more than any setting in the interface.
If you do only two things from this guide, do these: write the twenty-question evaluation set before you tune anything, and always click into the citations before deciding what is broken. Those two habits will take you further with RAGFlow than any amount of configuration.
Get one small knowledge base genuinely trustworthy before you build a second. A RAGFlow deployment that answers fifty questions reliably is worth far more than one that answers five hundred questions unpredictably.
Frequently Asked Questions
How long until I have something useful?
An afternoon to a working demo with real documents. About a week of part-time tuning to something you would let a colleague use unsupervised.
Can I run RAGFlow without an API key?
Yes. Connect a local model server instead of a hosted provider and the entire pipeline runs offline. Expect slower responses and somewhat weaker answers unless you have capable hardware.
How many documents can it handle?
Thousands comfortably on modest hardware. Tens of thousands with more resources and patience during parsing. The practical limit is usually parsing throughput, not retrieval.
Why are my answers worse than ChatGPT?
Because retrieval is doing the work, not the model. If the right context is not retrieved, no model can rescue the answer. Check your citations before blaming the model – this is the mistake nearly every beginner makes first.
Do I need a GPU?
Not to start. A GPU speeds up document parsing considerably and is worth it once your corpus grows past a few thousand files.
Can I change the embedding model later?
You can, but every document in that knowledge base must be re-parsed and re-indexed. Decide early.
Is my data sent anywhere?
Documents stay on your infrastructure. If you use a hosted model, the retrieved chunks are sent to that provider at query time. Use a local model to keep everything internal.